Applied prototype
Advotac
Indian legal research with OCR, structured legal documents, and Qdrant retrieval.
Problem & contribution
I built an AWS-hosted legal research system covering approximately 860 Central Acts and legal judgments. The work combined document processing and retrieval for Indian legal material.
Legal retrieval architecture
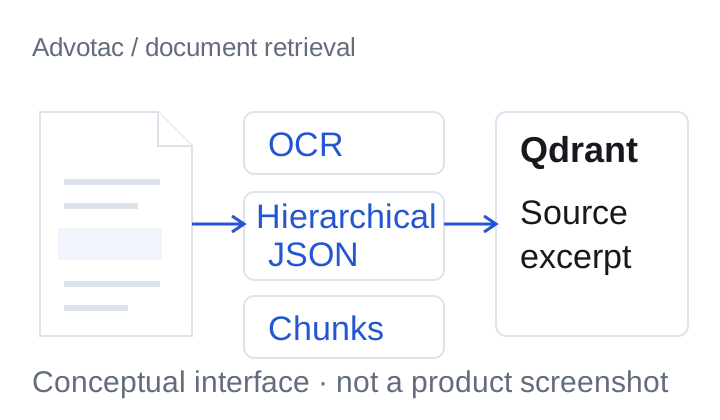
- Ingest & read. Legal acts and judgments, with OCR for scanned material.
- Structure & chunk. Hierarchical JSON and alternative chunking approaches.
- Retrieve. Vector retrieval with Qdrant.
Results & available evidence
The available record documents the system scope and experiments with chunking. A public retrieval benchmark and measured legal-answer accuracy are not available.
Scope documented in my résumé. No public performance benchmark is claimed.
Limitations & evaluation next steps
Scanned-text quality and chunk boundaries affect the context available to retrieval. A retrieved passage still needs source checking and legal judgment. A labeled evaluation set is needed to measure retrieval and answer quality.